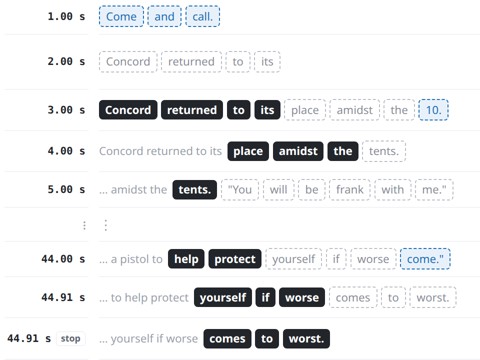
Whistle is a speech-to-text model from Cactus Compute: 55 million parameters and 16.9 MB on disk, covering seven languages (English, German, French, Spanish, Italian, Dutch and Polish). The weights are published under Apache-2.0, but the code that runs them is not. Upstream, in cactus-compute/needle, Whistle is a thin Python wrapper around a prebuilt, closed-source C++ engine. go-whistle is my pure-Go port: no cgo, no Python, no ONNX. It does transcription with language detection, keyword biasing, word timestamps, live streaming and embeddings, from a CLI, an HTTP/WebSocket server, a Go library, or a WebAssembly page in the browser.
Continue reading “go-whistle: Whistle speech-to-text in pure Go, rebuilt from the weights”Category: AI
kolibri-llama-cpp: Aleph Alpha’s Kolibri-1 in llama.cpp
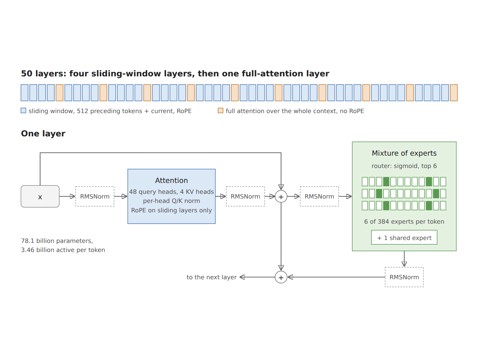
Aleph Alpha has released Kolibri-1, a mixture-of-experts language model with 78 billion parameters, of which only about 3.5 billion are active per token. That ratio makes it a candidate for a laptop, yet Aleph Alpha’s own way to run it is a plugin for vLLM, an inference server built for data-centre GPUs. kolibri-llama-cpp brings Kolibri to llama.cpp instead. The goal is a quantized build that runs on a Mac with 48 GB of unified memory and gives the same answers as Aleph Alpha’s reference. Quantized builds already run there, at up to 64 tokens per second.
Continue reading “kolibri-llama-cpp: Aleph Alpha’s Kolibri-1 in llama.cpp”